Thursday, 30 November 2023
Happy Birthday to ChatGPT
Saturday, 18 November 2023
Deep Fake Challenges for Libraries
Overall, deep fakes pose a number of challenges for libraries. Libraries need to be aware of these challenges and develop strategies for addressing them. By doing so, libraries can help to ensure that they continue to be trusted sources of information and that they protect the privacy and security of their users.
In addition to the challenges listed above, deep fakes can also have a negative impact on trust and credibility. When people are exposed to deep fakes, it can make them less likely to trust information that they see or hear. This can have a negative impact on libraries, as people may be less likely to use library resources if they are not sure that the information is reliable.
Libraries can address the challenges posed by deep fakes by developing a number of strategies. These strategies include:
- Educating users about deep fakes: Libraries can educate users about deep fakes by providing them with information about how to identify and avoid deep fakes. This information can be provided through workshops, online tutorials, and other resources.
- Developing policies and procedures for dealing with deep fakes: Libraries can develop policies and procedures for dealing with deep fakes. These policies may include procedures for reporting deep fakes, removing deep fakes from collections, and responding to requests from individuals who have been deepfaked.
- Collaborating with other organizations: Libraries can collaborate with other organizations, such as news organizations and social media companies, to develop strategies for addressing the challenges posed by deep fakes. This collaboration can help to raise awareness of the issue and to develop effective solutions.
By taking these steps, libraries can help to mitigate the negative impact of deep fakes and ensure that they continue to be trusted sources of information.
Friday, 17 November 2023
Over 3.5 Crore Pages From History Now Available At Click Of A Mouse
Arun Singhal, director general, NAI, told TOI that digitalising the archival content was aimed at making them accessible online across the globe for research work or personal interest. “The process of digitalisation of 70 lakh documents is under way and we hope to tackle the 30.5 crore pages in the next two years,” said Singhal, adding that downloading of the items will be chargeable though at a nominal fee.
Singhal said a tender has been floated for the remaining work, which is estimated to cost Rs 90 crore. The archives portal itself will be revamped for easier access. The search engine will be AI-based and will have premium features for researchers to facilitate exchange of documents with other researchers.
Among the rich collection of private papers at NAI are those of Mahatma Gandhi, Dadabhai Naoroji, M R Jayakar, Maulana Abul Kalam Azad, Gopal Krishna Gokhale and Minoo Masani. It also has the files of the Indian National Army and records acquired from Canada, Germany, Malaysia, Myanmar, United Kingdom, United States, France, Russia, etc.
“Private papers are donated either by a person or their family members, so we attach their names and call it a private archive. Public records come from various government departments,” explained Singhal. “Besides, we have inherited documents like Mughal dynasty records, including farmans of Noorjehan.” The oldest at the archives are the 6th century Buddhist texts called the Gilgit manuscripts.
The digitised collections include cartographic documents, like history, forest and revenue maps created by the Survey of India and other maps and atlases of Indian and foreign origins.
There also were ample papers related to Netaji Subhas Chandra Bose’s INA, also known as Azad Hind Fauj. The archived content comprises files, newspapers, registers , nominal rolls, photo albums, trial papers and many more important documents files which throw light on the history of the INA. These papers are among the most important and authentic primary sources of information for researchers.
An official said that the records and manuscripts form the basis of a country’s cultural heritage and in order to check the destruction of the collection of records stored in the archives, various conservation techniques and scientific methods were being employed to ensure preservation of these records.
Earlier, 1.5 crore pages were digitalised per year and it would have taken 20 years for the complete digitalisation. “But now we are digitalising 15 crore pages per year. However, the task is daunting as 15% of the items that we have on papers are so brittle that they cannot be scanned. We have to repair them and the process, besides being expensive, is time consuming,” said Singhal, adding that one repairer is able to handle 1,000 sheets, each with two sides, per month.
Friday, 10 November 2023
Easily generate bibliometric insights—without coding
Data Fetcher(opens in new tab/window) is the name for a free API(opens in new tab/window) query tool available for users associated with institutions that subscribe to Scopus and/or SciVal. An API, or “Application Programming Interface” is an intermediary software program that gives users the option to pull datasets from a given platform (like Scopus) in a custom format that’s not available through the main platform interface. This comes in handy if you want to analyze bibliometric information from a platform like Scopus but the dataset is too large, or you have a set of linked metadata you want to query from different platforms – combining Scopus and SciVal data, for example.
Sunday, 5 November 2023
Libraries and ChatGPT
Virtual Reference Services: Libraries can integrate ChatGPT into their websites or online catalogs to provide virtual reference services. Patrons can chat with ChatGPT to ask questions, seek information, and receive assistance with library resources.
Chatbots for FAQs:ChatGPT can be used to develop chatbots that answer frequently asked questions (FAQs). Patrons can interact with the chatbot to find information about library hours, policies, services, and more.
Information Retrieval:ChatGPT can assist patrons in searching for books, articles, and other resources in the library's catalog or databases. It can provide search tips and help users refine their queries.
Reading Recommendations:ChatGPT can offer personalized reading recommendations based on patrons' preferences, reading history, and interests. This can help users discover new books and authors.
Programming and Event Promotion:Libraries can use ChatGPT to promote upcoming events, workshops, and programs. Patrons can inquire about event details and registration through the chat interface.
Language Translation: ChatGPT can assist with language translation services, making library materials more accessible to a diverse community.
Accessibility Services: ChatGPT can provide information on the accessibility services available at the library, such as assistive technology, accessible formats, and accommodations for patrons with disabilities.
Library Policies and Procedures: ChatGPT can help patrons understand library policies, such as borrowing rules, interlibrary loans, and overdue fines. It can also guide users through various library procedures.
Information Literacy: Libraries can use ChatGPT to offer guidance on information literacy skills, including evaluating sources, citing references, and avoiding plagiarism.
Content Summaries: ChatGPT can provide brief summaries or abstracts of articles, research papers, or books, helping patrons decide whether a resource is relevant to their needs.
When implementing ChatGPT in a library setting, it's essential to ensure that the chatbot or virtual assistant is designed to complement human library staff and not replace them entirely. Human librarians can still provide valuable in-depth assistance and expertise that AI may not replicate. Additionally, privacy and data security considerations should be taken into account when using AI in libraries.
Friday, 20 October 2023
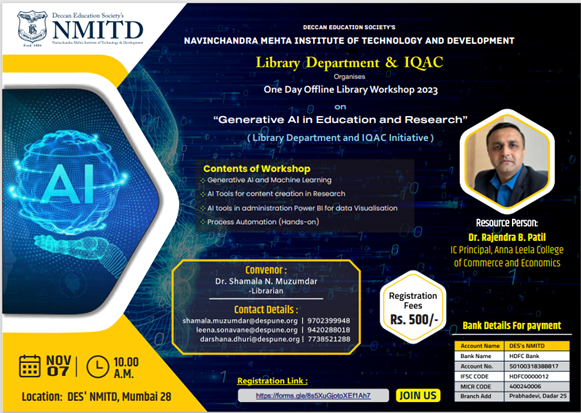
Workshop on " Generative AI in Education and Research " on 7th November 2023
♦️ Resource Persons: Dr. Rajendra B. Patil, IC Principal, Anna Leela College of Commerce and Economics
🗒 Date: Tuesday, 7th November, 2023
🕚 Time: 10.00 a.m. to 05:00 p.m.
🔺 Registration fee: Rs. 500/- (Inclusive All)
📯 Registration is Compulsory!
🔗 Registration link: https://forms.gle/8s5XuGjotoXEf1Ah7
🔺 Venue: DES’s Navinchandra Mehta Institute of Technology and Development, Dadar (W),
Mumbai 28.
🔺 Workshop includes high tea and Lunch.
Dr. Anita Bobade, In-Charge-Director, NMITD.
Dr. Rasika Mallya, Assoc. Director and IQAC Coordinator, NMITD.
Dr. Shamala Muzumdar, Convener and Librarian, NMITD.
Discussion on "Academic Integrity: The Way Forward with AI"
Turnitin, which has provided the world’s most adopted writing-to-learn products to more than 16000 institutions across 140 countries, would like to invite you to a discussion on "Academic Integrity: The Way Forward with AI", to commemorate the IDOA International Day of Action(18th October) for Academic Integrity.
- What is Academic Integrity & Original Writing?
- Define plagiarism, the plagiarism spectrum and understand the difference between plagiarism and text similarity
- Understand the guidelines around Academic Integrity by the Indian education governance bodies
- GPT and its impact
- Where are we headed given the latest concerns coming from generative AI?
- Role of Turnitin
Saturday, 14 October 2023
Workshop on Artificial Intelligence and Libraries: Implications and Applications" organized by Indira Gandhi Institute of Development and Research (IGIDR), Mumbai
I consider
myself very fortunate to have participated in today’s mesmerizing workshop!
The workshop on "Artificial
Intelligence and Libraries: Implications and Applications" organized by
Indira Gandhi Institute of Development and Research (IGIDR) gathered
professionals from the library and information science field to delve deep into
the world of Artificial Intelligence (AI) and explore its present landscape and
future applications in libraries. The event focused on generative AI tools such
as ChatGPT, Bing Chat, DALL-E, and Scopus AI, as well as AI-enabled research
tools. This report provides a summary of the key insights and discussions from
the workshop, emphasizing the potential of AI to transform library operations,
services, and knowledge management.
1. AI in Libraries: Landscape
and Future
The workshop began with an
overview of the current state of AI in libraries. Participants discussed the
rapid advancement of AI technologies and their relevance in libraries.
The future of AI in libraries
was explored, considering its implications for resource discovery, user
engagement, and data-driven decision-making.
2. Generative AI and Libraries by
ChatGPT/Google Bard:
Participants gained insights into the use of conversational AI for enhancing
user experiences, enabling quick responses to queries, and guiding users
through library resources.
Bing Chat: The potential of Bing
Chat in providing instant, AI-driven support to library users was highlighted,
along with its ability to enhance user media literacy.
Stable Diffusion/Bing Image
Generator (DALL-E): The workshop discussed how tools like DALL-E can revolutionize
content creation and visualization, making library operations more efficient
and user-centric.
3. Scopus AI: Change the Way You
View Knowledge
Participants explored how AI,
particularly in the context of Scopus AI, is poised to change the way knowledge
is indexed, searched, and accessed in library databases.
The workshop emphasized the
importance of libraries adapting to these changes and leveraging AI
technologies to enhance their services and support research activities.
4. AI-enabled Research Tools
The workshop provided an
opportunity to delve into AI-enabled research tools that have the potential to
revolutionize research endeavors in libraries.
Participants discussed the
skills needed to effectively utilize these tools, both for their own research
and for educating and empowering library users.
To conclude….
The "AI in Libraries"
workshop facilitated a deep dive into the evolving landscape of AI in
libraries. It highlighted the promising future of AI, focusing on generative AI
tools and AI-enabled research platforms. The event emphasized the importance of
adapting to these technologies to improve library operations, provide better
services, and support research activities effectively.
Participants left the workshop
with a greater understanding of how AI tools like ChatGPT, Bing Chat, DALL-E,
and Scopus AI can be harnessed to enhance their libraries. The knowledge and
skills acquired during the workshop will be instrumental in staying at the
forefront of library services and research support in the age of AI. Future
workshops and initiatives were proposed to ensure ongoing education and
collaboration in this dynamic field.
Thursday, 23 March 2023
Try BARD
Today we’re starting to open access to Bard, an early experiment that lets you collaborate with generative AI. This follows our announcements from last week as we continue to bring helpful AI experiences to people, businesses and communities.
You can use Bard to boost your productivity, accelerate your ideas and fuel your curiosity. You might ask Bard to give you tips to reach your goal of reading more books this year
Read the full article at: https://blog.google/technology/ai/try-bard/
Thursday, 16 March 2023
ChatGPT and Fake Citations: Article from Duke University Libraries
Unless you’ve been living under a rock, you’ve heard the buzz about ChatGPT. It can write papers! Debug code! Do your laundry! Create websites from thin air! While it is an exciting tech development with enormous possibilities for applications, understanding what’s under the hood and what it does well/not-so-well is critically important.
ChatGPT is an Artificial Intelligence Chatbot developed by OpenAI and launched for public use in November 2022. While other AI chatbots are also in development by tech giants such as Google, Apple, and Microsoft, OpenAI’s early rollout has eclipsed the others for now – with the site reaching more than 100 million users in 2 months. For some perspective, this is faster widespread adoption than TikTok, Instagram, and many other popular apps.
What you may not know about ChatGPT is that it has significant limitations as a reliable research assistant. One such limitation is that it has been known to fabricate or “hallucinate” (in machine learning terms) citations. These citations may sound legitimate and scholarly, but they are not real.
Read the full article at: https://blogs.library.duke.edu/blog/2023/03/09/chatgpt-and-fake-citations/
Source: Duke University Library Blog